FIELD NOTE 014 / RAG FUNDAMENTALS
RAG Explained: How Retrieval-Augmented Generation Actually Works
A foundational explainer on Retrieval-Augmented Generation: chunking, embeddings, vector search, grounding, and why naive RAG hallucinates.
By Harrison Ndeke · Published September 20, 2026 · Updated September 20, 2026 · 11 min read
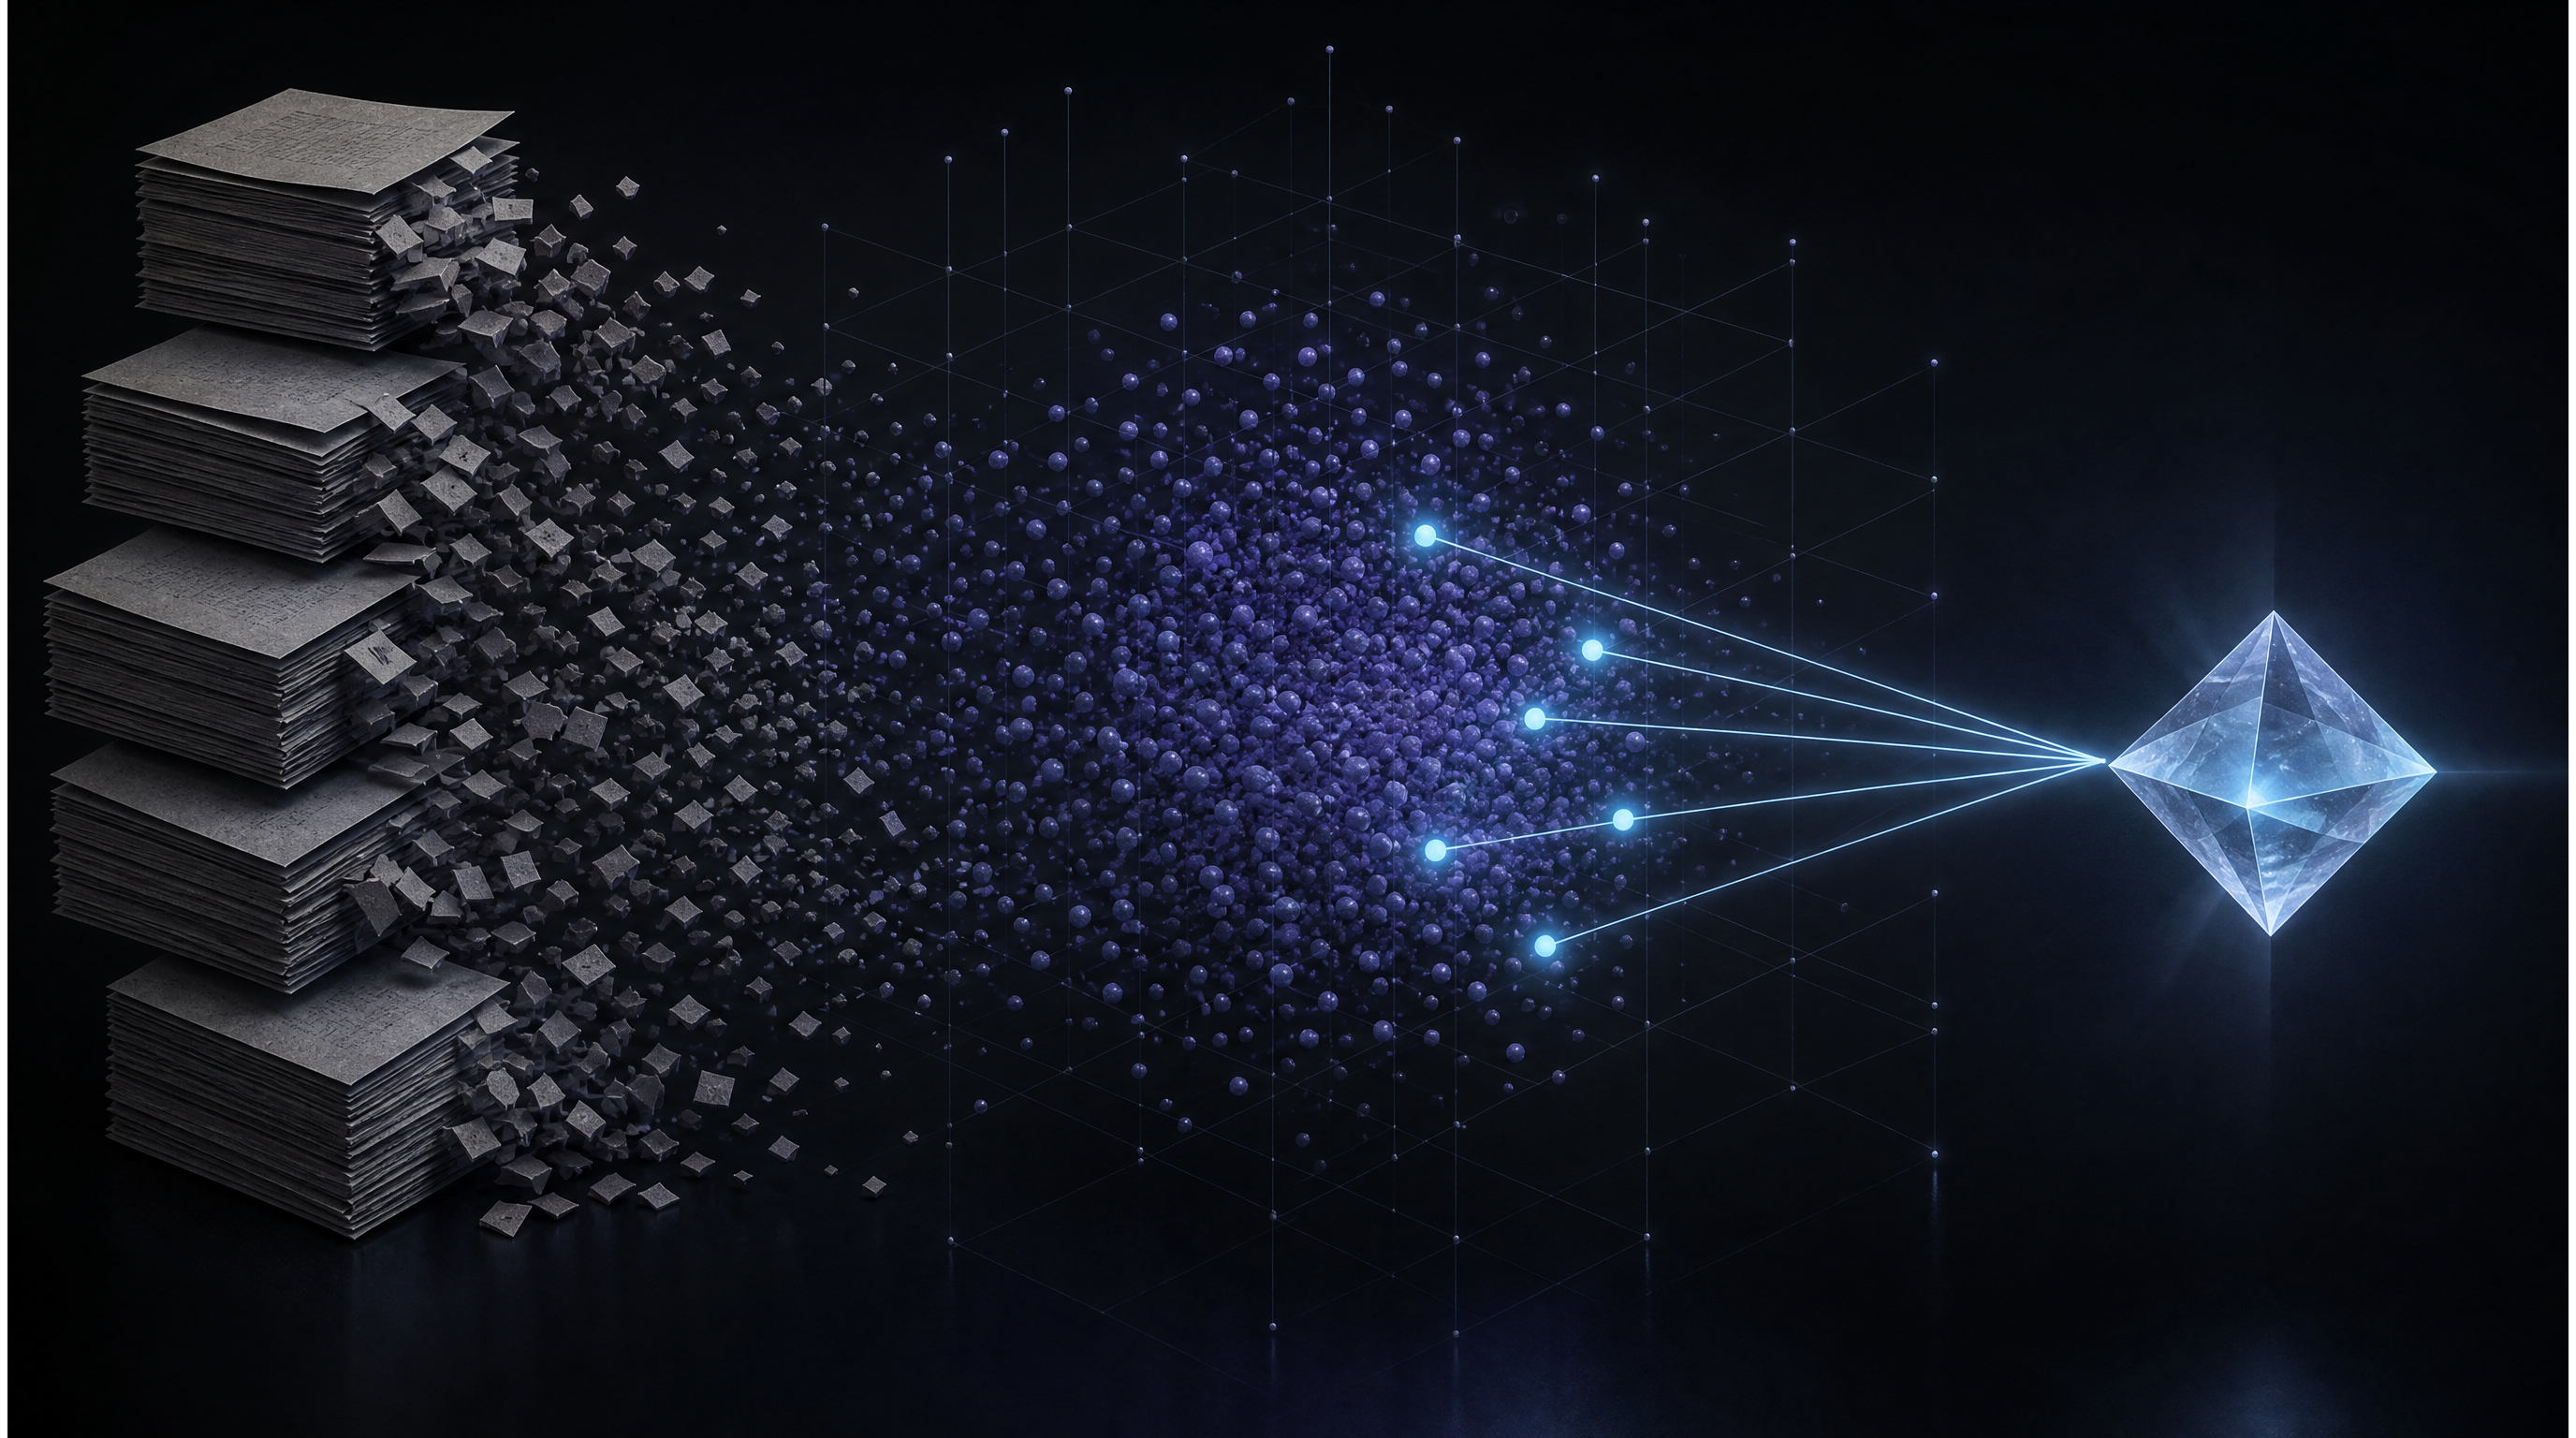
RAG PIPELINE
INGEST → CHUNK → EMBED → RETRIEVE → GROUND
DIRECT ANSWERRetrieval-Augmented Generation (RAG) connects a language model to an external knowledge source at query time instead of relying only on what the model memorized during training. Documents are split into chunks, converted into vector embeddings, and stored in a vector database; when a question arrives, the system embeds the question, retrieves the most similar chunks, and passes them to the model as context so it answers from that retrieved evidence rather than guessing. Most RAG failures come from bad chunking, stale or unfiltered sources, or retrieval returning the wrong context — not from the model itself.
Key takeaways
- RAG is a retrieval problem before it is a model problem: a perfect model with irrelevant retrieved context still produces a wrong answer.
- Chunking strategy matters more than most teams expect: chunks that are too large dilute relevance; chunks that are too small lose context.
- Embeddings capture semantic similarity, not truth: a highly similar chunk can still be outdated or wrong.
- Grounding requires the model to cite what it retrieved: without an explicit instruction to answer only from context, models still blend in memorized knowledge.
- Source freshness and access control are production concerns, not implementation details — an ungoverned RAG pipeline can leak access-restricted documents or serve stale answers with confidence.
What does the RAG pipeline actually look like?
Five stages, in order: ingestion, chunking, embedding, storage, and retrieval-plus-generation.
- Ingestion: pull documents from their source — a knowledge base, a database, a file store — and normalize them to plain text.
- Chunking: split each document into smaller passages, typically a few hundred tokens, often with some overlap between adjacent chunks so a fact split across a boundary isn't lost entirely.
- Embedding: convert each chunk into a numeric vector using an embedding model. Chunks with similar meaning end up close together in that vector space, regardless of exact wording.
- Storage: store the vectors and their source chunks in a vector database or a Postgres extension like pgvector, indexed for fast similarity search.
- Retrieval and generation: at query time, embed the user's question, find the nearest chunks by vector similarity, and pass those chunks plus the question to the language model as context for its answer.
Why does RAG still hallucinate?
Adding retrieval does not remove a model's tendency to generate plausible-sounding text — it changes what the model has available to ground its answer in. Three common failure modes:
| Failure mode | What happens | Mitigation |
|---|---|---|
| Wrong chunk retrieved | The nearest vector by similarity isn't actually the most relevant answer to the question. | Tune chunk size, add metadata filtering, use hybrid search (keyword + vector). |
| No retrieval instruction | The model blends retrieved context with its own training knowledge instead of prioritizing what was retrieved. | Explicit system prompt: answer only from provided context; say so when the context is insufficient. |
| Stale or conflicting sources | Two retrieved chunks disagree, or the retrieved chunk was correct a year ago and isn't now. | Track last-updated timestamps, prefer newer sources, flag conflicts instead of silently picking one. |
A RAG system that returns a confident answer with no indication of source or freshness is not more trustworthy than a model with no retrieval at all — it just sounds more trustworthy.
What does "grounding" mean in practice?
Grounding means the model's answer is verifiably derived from the retrieved context, not just plausible given it. In practice this means three things in the system prompt and pipeline design: instruct the model to answer strictly from the provided passages, require it to say when the context doesn't contain an answer instead of filling the gap from memory, and attach citations — which chunk, which document, which timestamp — so an answer can be checked against its source.
SYSTEM: Answer only using the CONTEXT below.
If the context does not contain the answer, say so explicitly.
Cite the source document for every claim.

CONTEXT:
[retrieved chunks with source + timestamp metadata]

QUESTION: {user_question}
When is RAG the wrong tool?
RAG solves "the model needs facts it wasn't trained on, or facts that change over time." It does not solve problems better handled by fine-tuning (teaching a model a consistent style or narrow skill), structured lookups (a direct database query is more reliable than embedding-similarity search for exact-match facts like an order status), or reasoning tasks that don't depend on external documents at all. Reaching for RAG by default, even when a simple API call or SQL query would answer the question deterministically, adds latency and a new failure surface for no benefit.
Executive summary
RAG's real engineering surface is the retrieval half of the pipeline, not the generation half — chunking strategy, embedding quality, metadata filtering, source freshness, and explicit grounding instructions determine whether the system is reliable. A production RAG pipeline treats retrieval accuracy as something to measure and test, not something to assume once the vector database is wired up.
Related services and reading
- RAG Developer for production Retrieval-Augmented Generation pipeline builds.
- RAG source freshness, provenance, and access control for the production governance layer on top of this foundation.
- Defending RAG agents against indirect prompt injection for the security implications of retrieving untrusted content.
- Supabase for AI for a concrete pgvector-based storage layer.
About the author
Harrison Ndeke is an AI automation developer in Nairobi building production RAG pipelines on Supabase pgvector with source-freshness checks and access-control-aware retrieval. Public work includes the Standout4Growth RAG chatbot.
Sources, scope, and limitations
This explainer describes general RAG architecture as commonly implemented with tools like Supabase's pgvector integration and standard embedding models. It does not claim a specific retrieval-accuracy benchmark; accuracy depends entirely on chunking, embedding model choice, and evaluation against a real test set for the specific document domain.